
AI-Docu-Mind: Multimodal & Local RAG Document Intelligence Engine
An enterprise-grade, privacy-first Retrieval-Augmented Generation (RAG) and Document Intelligence platform featuring multi-format parsing, hybrid vector retrieval, real-time SSE streaming, and local air-gapped LLM orchestration.
The Enterprise Knowledge Dilemma: Precision and Privacy
In mission-critical business environments across legal, engineering, and financial sectors, unstructured documents such as contracts, engineering specifications, and compliance audits form the foundation of institutional knowledge. While Large Language Models have advanced significantly, deploying them directly against enterprise corpora presents substantial architectural and operational risks.
First, standard LLMs suffer from uncontrollable hallucinations, producing answers that sound confident while misrepresenting core contractual facts or numerical thresholds. Second, enterprise compliance standards frequently prohibit transmitting proprietary documents to external cloud APIs, demanding strictly air-gapped, on-premise execution. Third, standard semantic vector search often fails to match exact alphanumeric codes, technical acronyms, or specific currency figures due to embedding dimensionality loss.
Hybrid Architecture: Engineering High-Precision Ingestion and Retrieval
To resolve these limitations, I engineered AI-Docu-Mind as an autonomous, privacy-first Document Intelligence Engine that operates seamlessly without external cloud dependencies:
The ingestion pipeline incorporates dedicated structural parsers supporting PDF, DOCX, CSV, Markdown, and JSON. Extracted text undergoes metadata normalization, including deterministic SHA-256 document fingerprinting, automated heading detection, and token estimation to prevent redundant indexing and guarantee data lineage.
Text partitioning is handled by an intelligent recursive character chunker utilizing a sliding overlap window. By executing a hierarchical fallback across paragraph breaks, line breaks, sentence delimiters, and whitespace, the system preserves context continuity across chunk boundaries without splitting logical thoughts or tabular rows.
To eradicate retrieval drift, the query pipeline implements a dual-layer hybrid search combining dense semantic cosine similarity with lexical BM25 re-ranking. A calibrated scoring function balances conceptual semantic matching with exact keyword density, ensuring that high-level inquiries and specific clause references surface with equal precision.
Multi-Provider Orchestration and Anti-Hallucination Guardrails
The synthesis pipeline applies strict validation layers to ensure answers remain strictly grounded within retrieved evidence:
Operational Interfaces and Production Readiness
The platform is designed to provide equal ergonomics for operations teams, analysts, and software engineers:
The web interface features a dark glassmorphism dashboard equipped with drag-and-drop document uploads, real-time vector collection telemetry, and interactive citation drawers that highlight corresponding source excerpts on demand.
For automation workflows, the system provides a comprehensive command line interface built with Typer and Rich for batch indexing and terminal queries, accompanied by a production-ready FastAPI REST service fully documented via OpenAPI standards and containerized with Docker for rapid cloud and on-premise deployments.
Click any screen below to inspect in high-resolution with zoom in, zoom out, pan, and full screen controls.
 01
Interactive RAG Workspace & Grounded Streaming
Real-time token streaming via Server-Sent Events with interactive citation cards and verifiable document evidence.
 02
FastAPI REST Gateway & OpenAPI Documentation
High-throughput endpoints for document ingestion, collection management, and streaming question answering.
Interested in a similar project?
We can build a tailored solution customized to your business goals.
Explore Related Work
Production software, AI tools, and enterprise platforms.
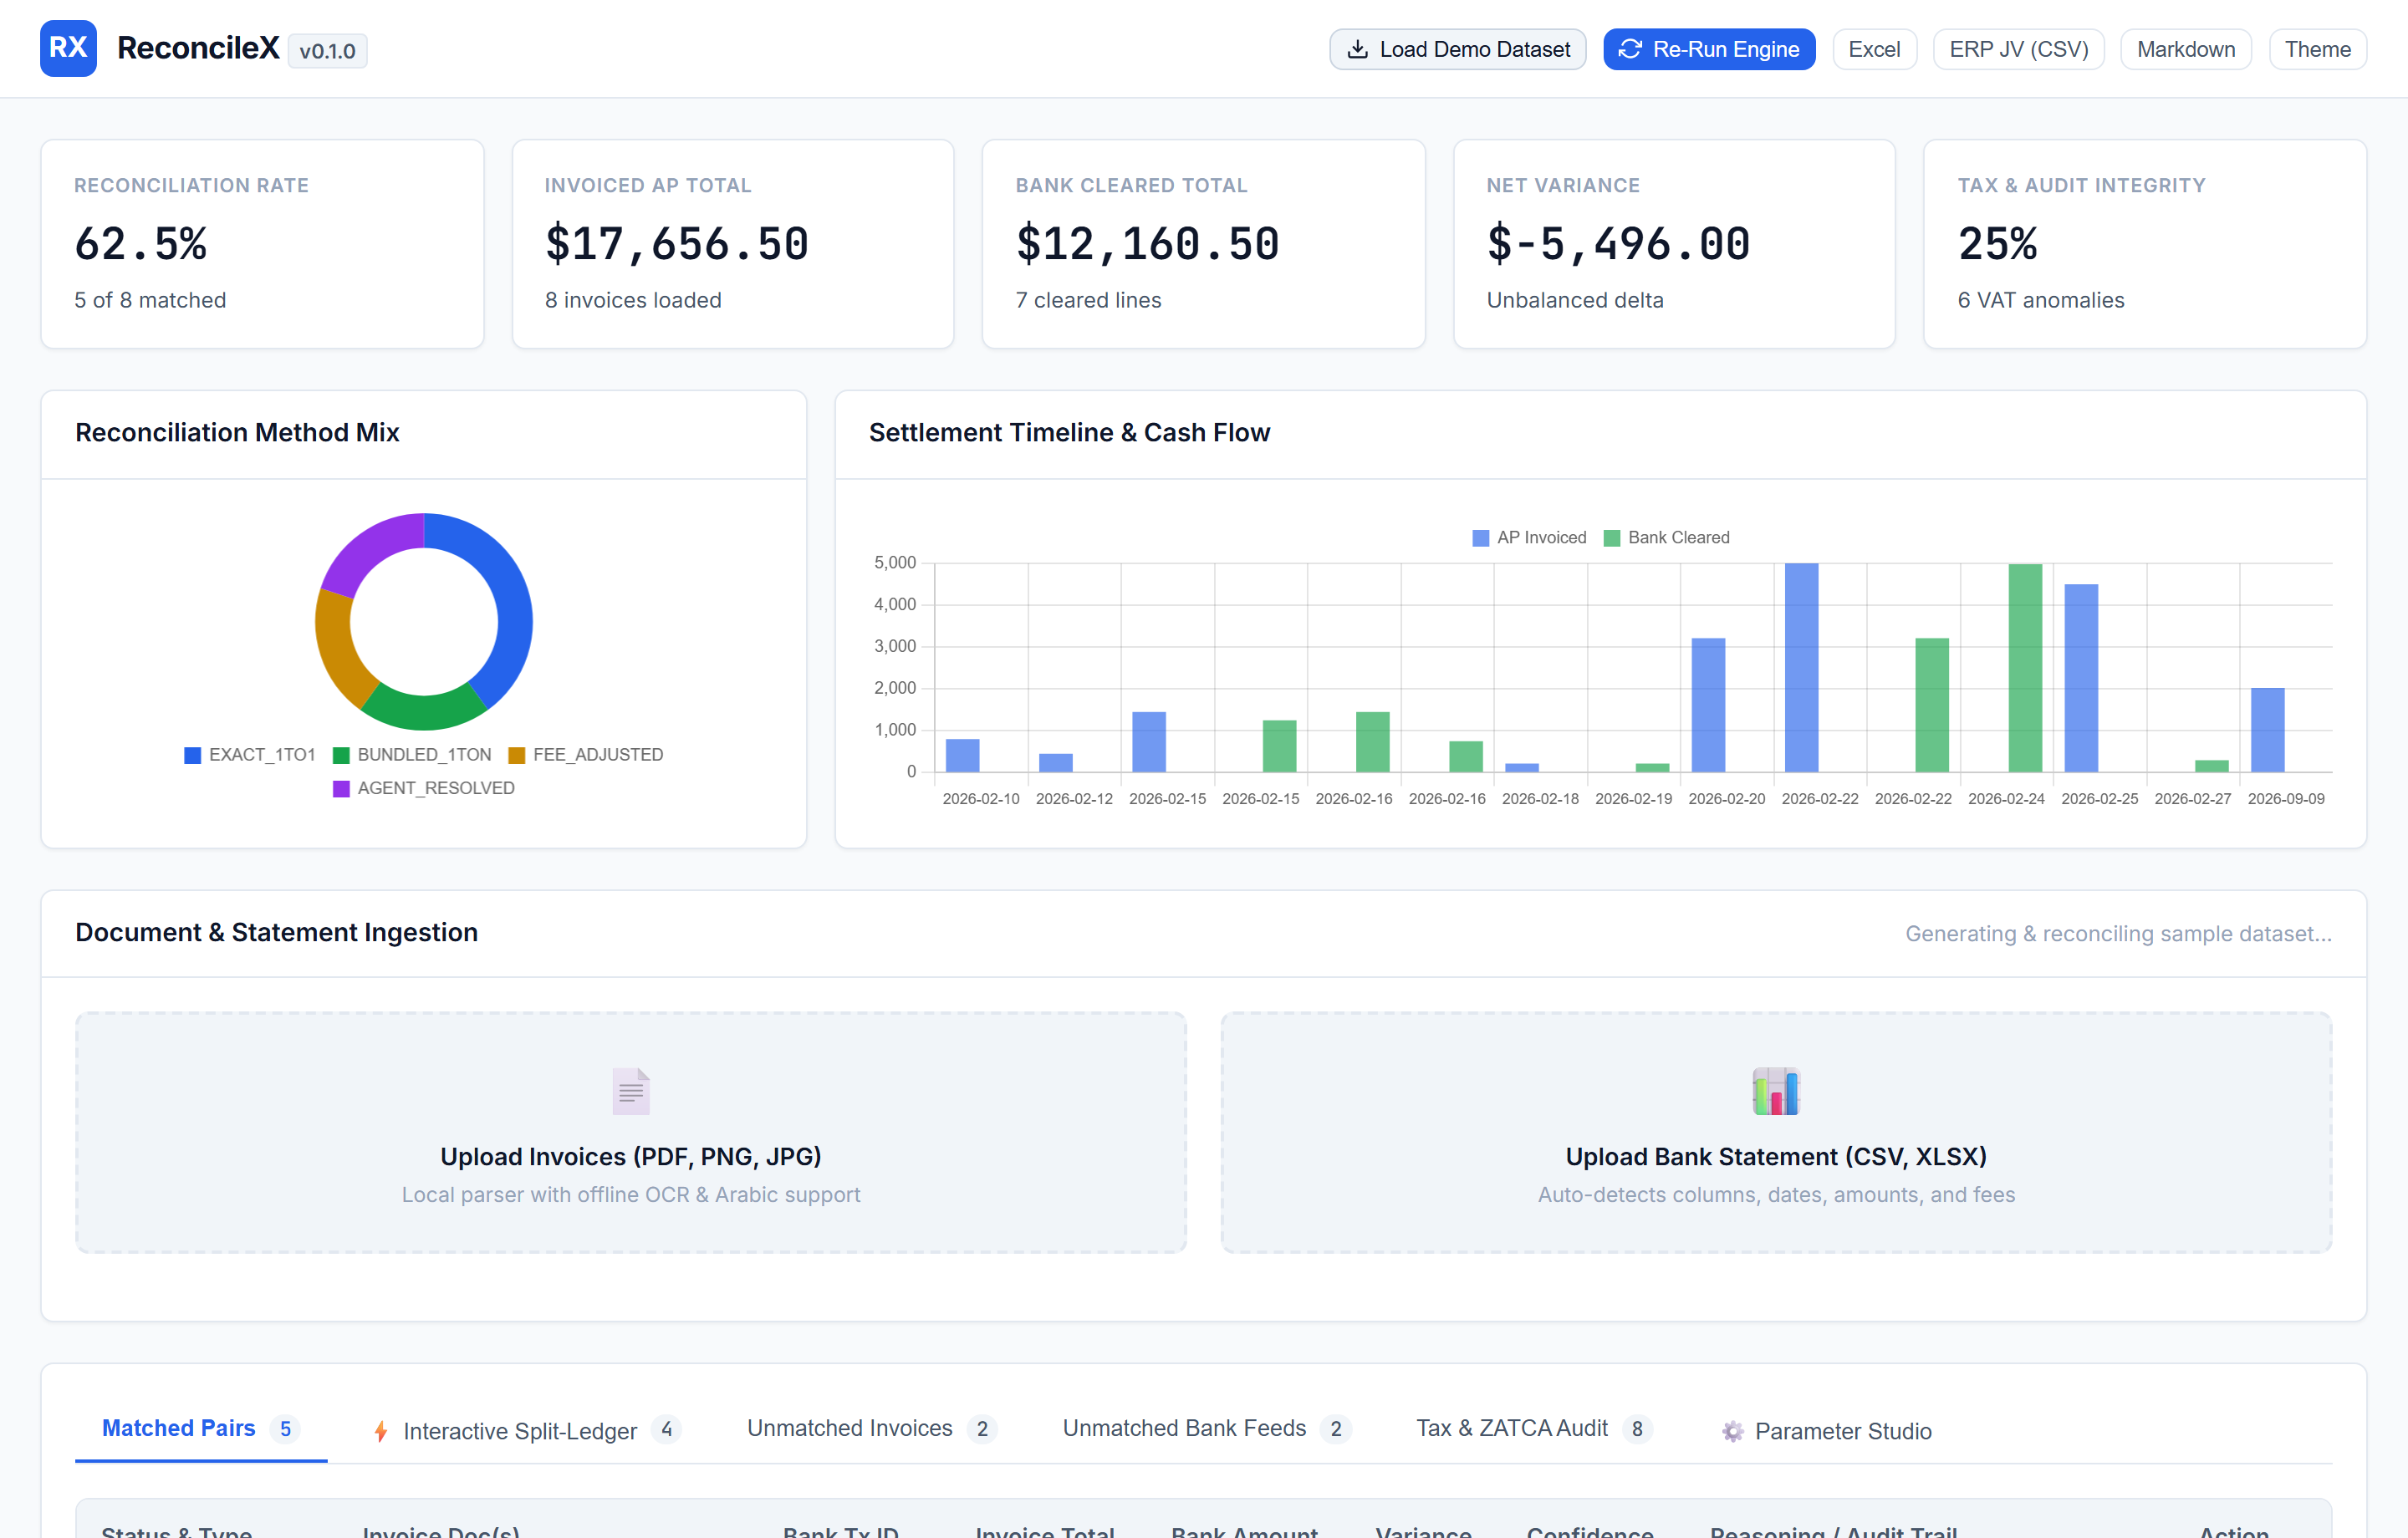 ERP & Enterprise Systems
ReconcileX: Enterprise Financial Reconciliation & ZATCA Tax Compliance Platform with Hybrid Deterministic Architecture
An enterprise-grade open-source financial reconciliation engine engineered to eliminate manual spreadsheet matching, combining deterministic zero-hallucination arithmetic with agentic reasoning to resolve bundled batch payouts, ZATCA VAT compliance audits, and balanced ERP journal vouchers.
 Cloud Engines & Infrastructure
PeerWarp: Zero-Cloud P2P Direct File Transfer Platform
An open-source, production-grade file transfer platform engineered to move unlimited files and folders directly between browsers via encrypted WebRTC DataChannels, eliminating cloud storage intermediaries with direct-to-disk writing, on-the-fly compression, and local Wi-Fi radar.
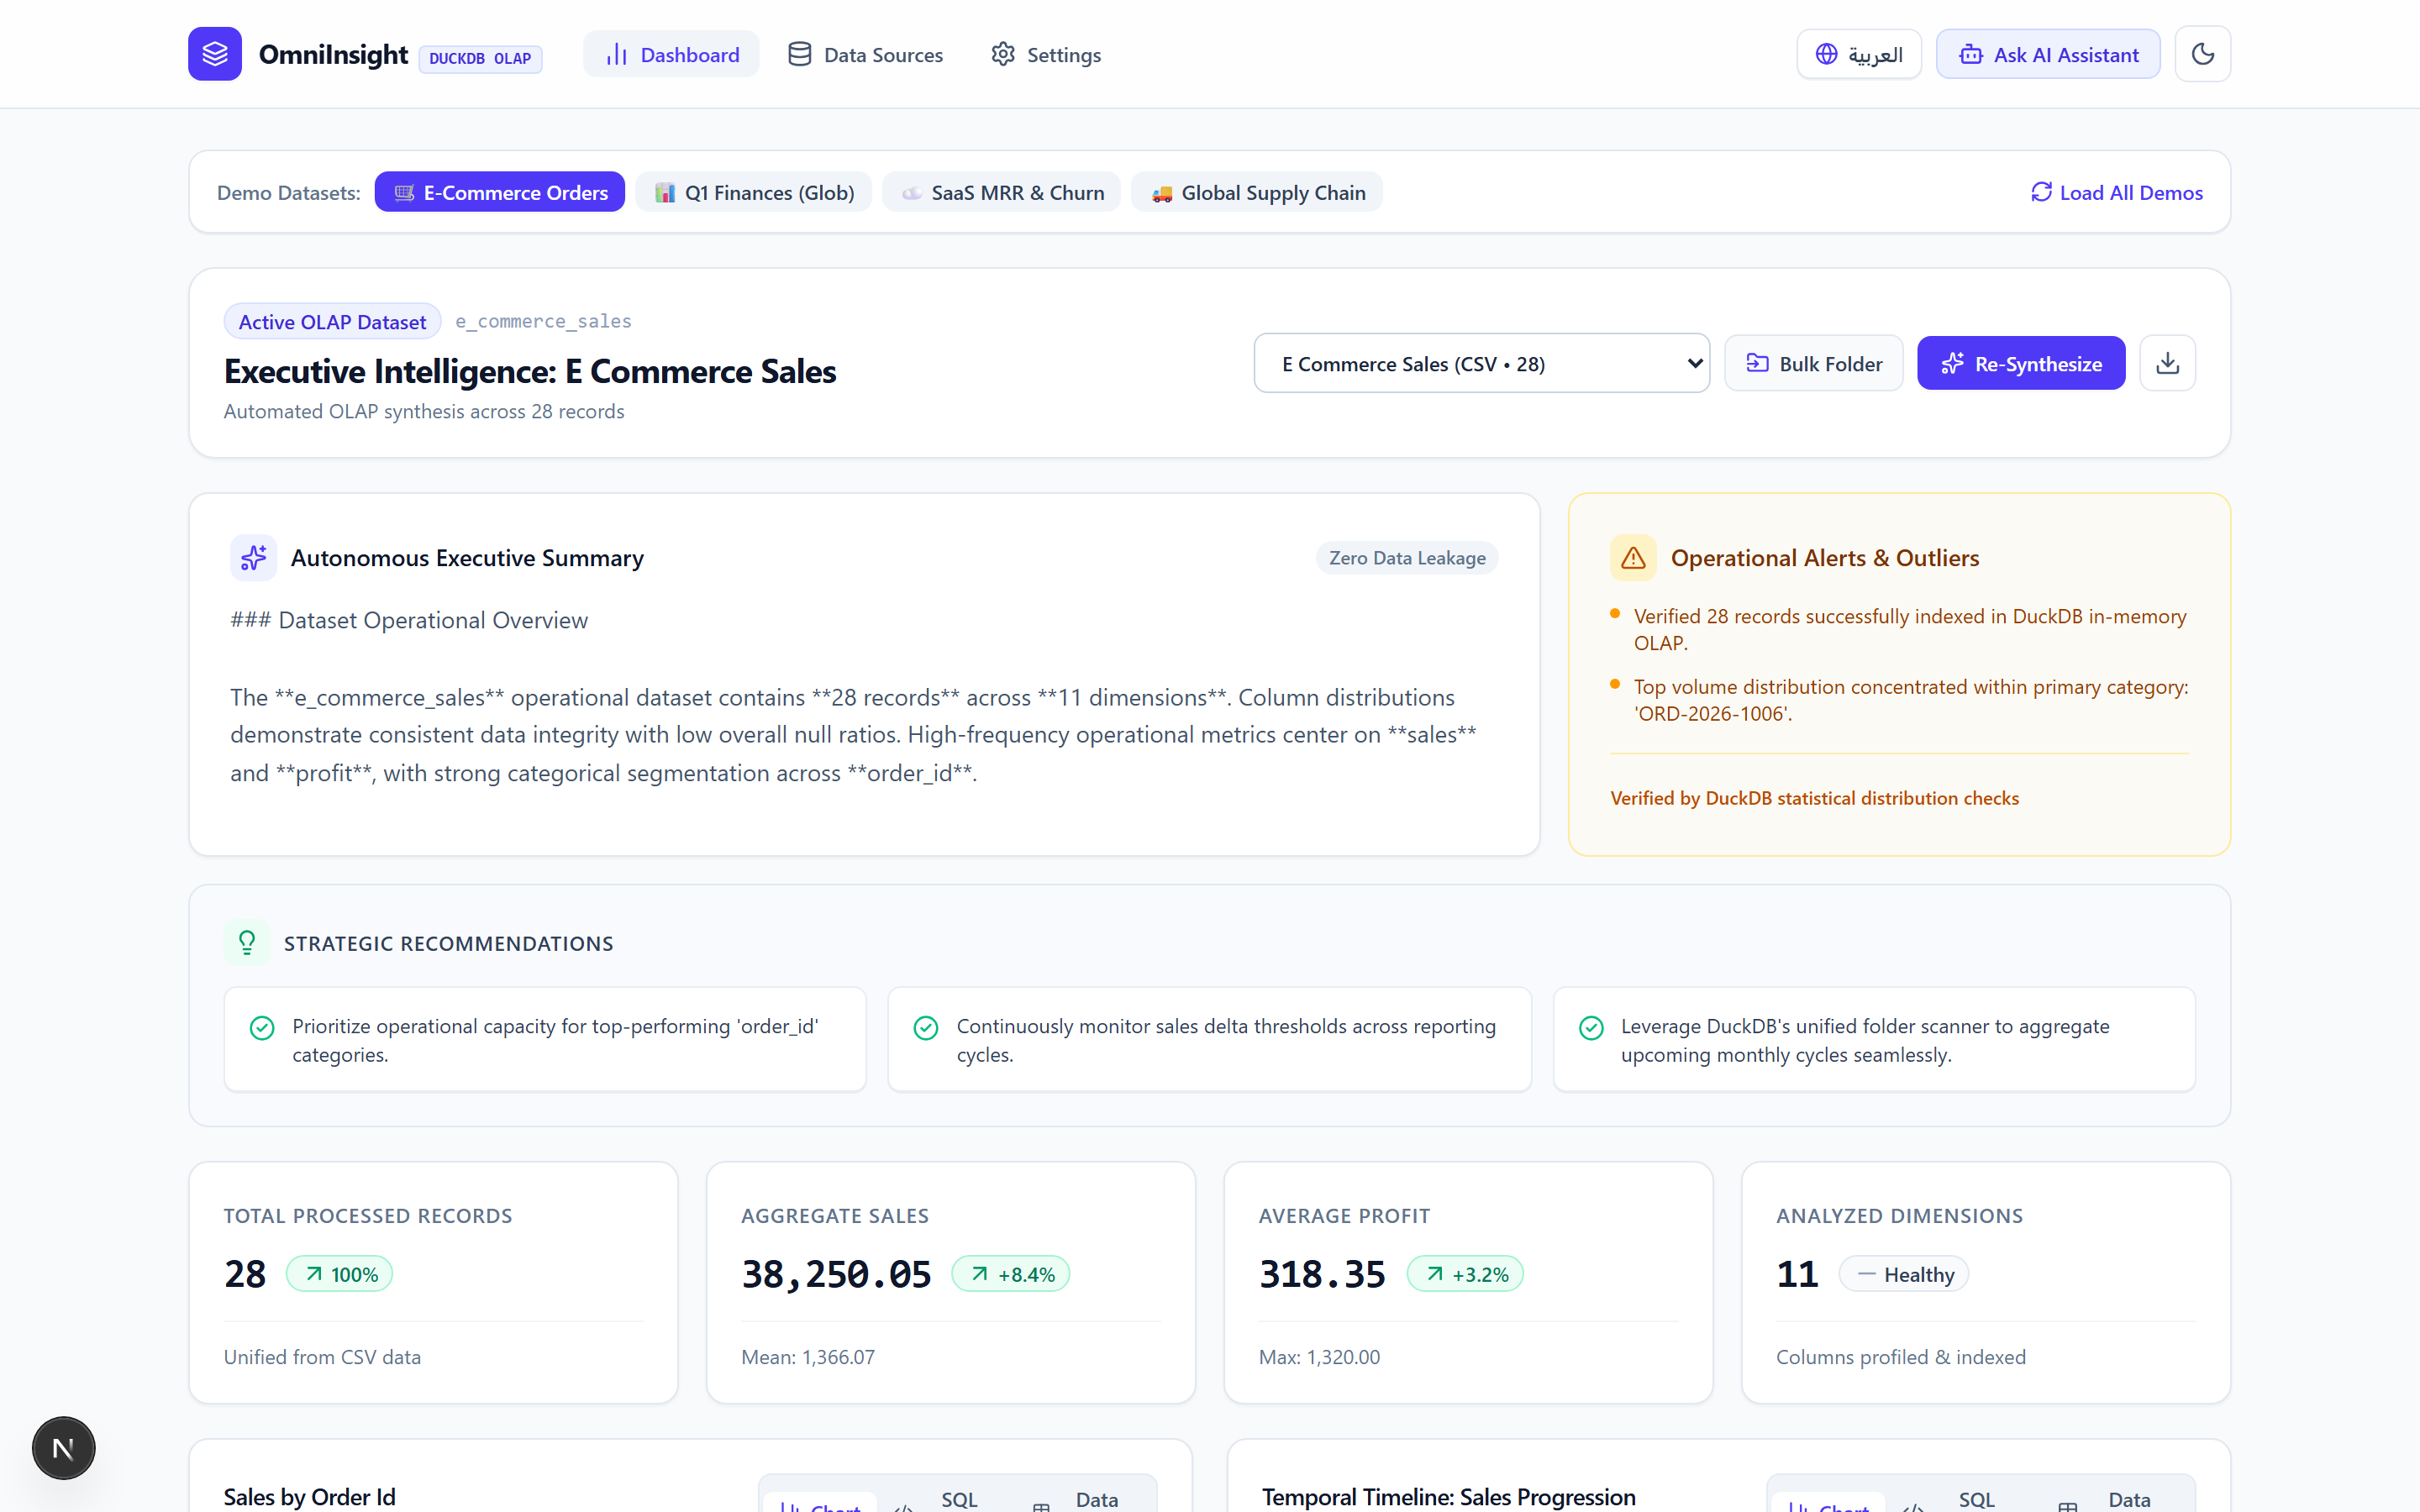 AI & Automation
OmniInsight: Privacy-Preserving Local BI & Automated Analytics Platform with In-Memory DuckDB and Multi-LLM Reasoning
An open-source, local-first Business Intelligence platform engineered to replace proprietary cloud BI tools, pairing DuckDB's vectorized in-memory OLAP engine with privacy-safe LiteLLM reasoning to autonomously synthesize executive dashboards and answer conversational NLQ queries with zero data leakage.