
Omni-Scraper: Enterprise Web Automation & Resilient ETL Data Extraction Pipeline
A high-performance, fault-tolerant web automation and ETL data extraction engine engineered for dynamic websites, featuring anti-bot resilience, User-Agent rotation, declarative schema parsing, and SHA-256 deduplication.
The Big Data Ingestion Dilemma: Why Fragile Web Scrapers Break in Production
Modern market intelligence platforms, price aggregators, and enterprise analytics teams depend on continuous data streams harvested from complex e-commerce catalogs, job boards, and digital marketplaces. Yet traditional scraping scripts frequently collapse under production workloads due to three critical engineering failure modes.
First, modern anti-bot protection mechanisms analyze request heuristics and immediately block scraper IP addresses when they encounter repetitive HTTP fingerprints or uniform request intervals. Second, recurrent scraping missions inadvertently flood downstream data lakes with duplicate records, wasting database disk space and skewing analytic calculations. Third, unmanaged request concurrency causes abrupt rate limit throttling with HTTP 429 and 503 errors, terminating long-running scraping runs midway without persisting retrieved records.
Resilient Asynchronous Architecture: Concurrency with Defensive Rate Limiting
To overcome these ingestion vulnerabilities, I architected Omni-Scraper-Engine as an enterprise-grade extraction pipeline pairing high concurrency with robust fault tolerance:
The core network layer is powered by an asynchronous httpx client featuring intelligent connection pooling, enabling hundreds of concurrent non-blocking HTTP requests without exhausting system resources. To prevent destination server overload, the ingestion engine applies a Token Bucket algorithm combined with adaptive full-jitter exponential backoff, automatically smoothing out traffic spikes and absorbing transient network drops.
The engine also incorporates an active anti-detection layer that cycles realistic desktop and mobile User-Agent strings alongside modern browser client hints such as security headers and preferred display languages, ensuring requests mirror genuine human browsing sessions.
Declarative Schema Parsing, Cryptographic Deduplication, and Data Lake Persistence
Beyond raw HTML ingestion, the engine routes raw payloads through a structured transformation and normalization pipeline:
Dual Interface: Interactive Dark Studio and Automated CLI Tooling
Omni-Scraper delivers versatile developer ergonomics catering to both interactive exploration and headless infrastructure pipelines:
The platform features a modern dark-mode glassmorphism web studio where engineers can launch new scraping missions, view worker telemetry, track memory usage, and inspect extracted records in a responsive data table with full sorting and filtering capabilities.
For automated server deployments, the project provides a comprehensive CLI powered by Typer and Rich, allowing DevOps teams to schedule automated cron jobs and pipeline triggers, accompanied by a fully documented FastAPI REST layer adhering to OpenAPI standards.
Click any screen below to inspect in high-resolution with zoom in, zoom out, pan, and full screen controls.
 01
Scraper Mission Control Center
Real-time crawler orchestration dashboard tracking proxy pool health, active jobs, and the extracted data lake.
 02
FastAPI High-Throughput REST API
Interactive OpenAPI documentation supporting asynchronous job dispatches and streaming data downloads in CSV and JSONL.
Interested in a similar project?
We can build a tailored solution customized to your business goals.
Explore Related Work
Production software, AI tools, and enterprise platforms.
 Cloud Engines & Infrastructure
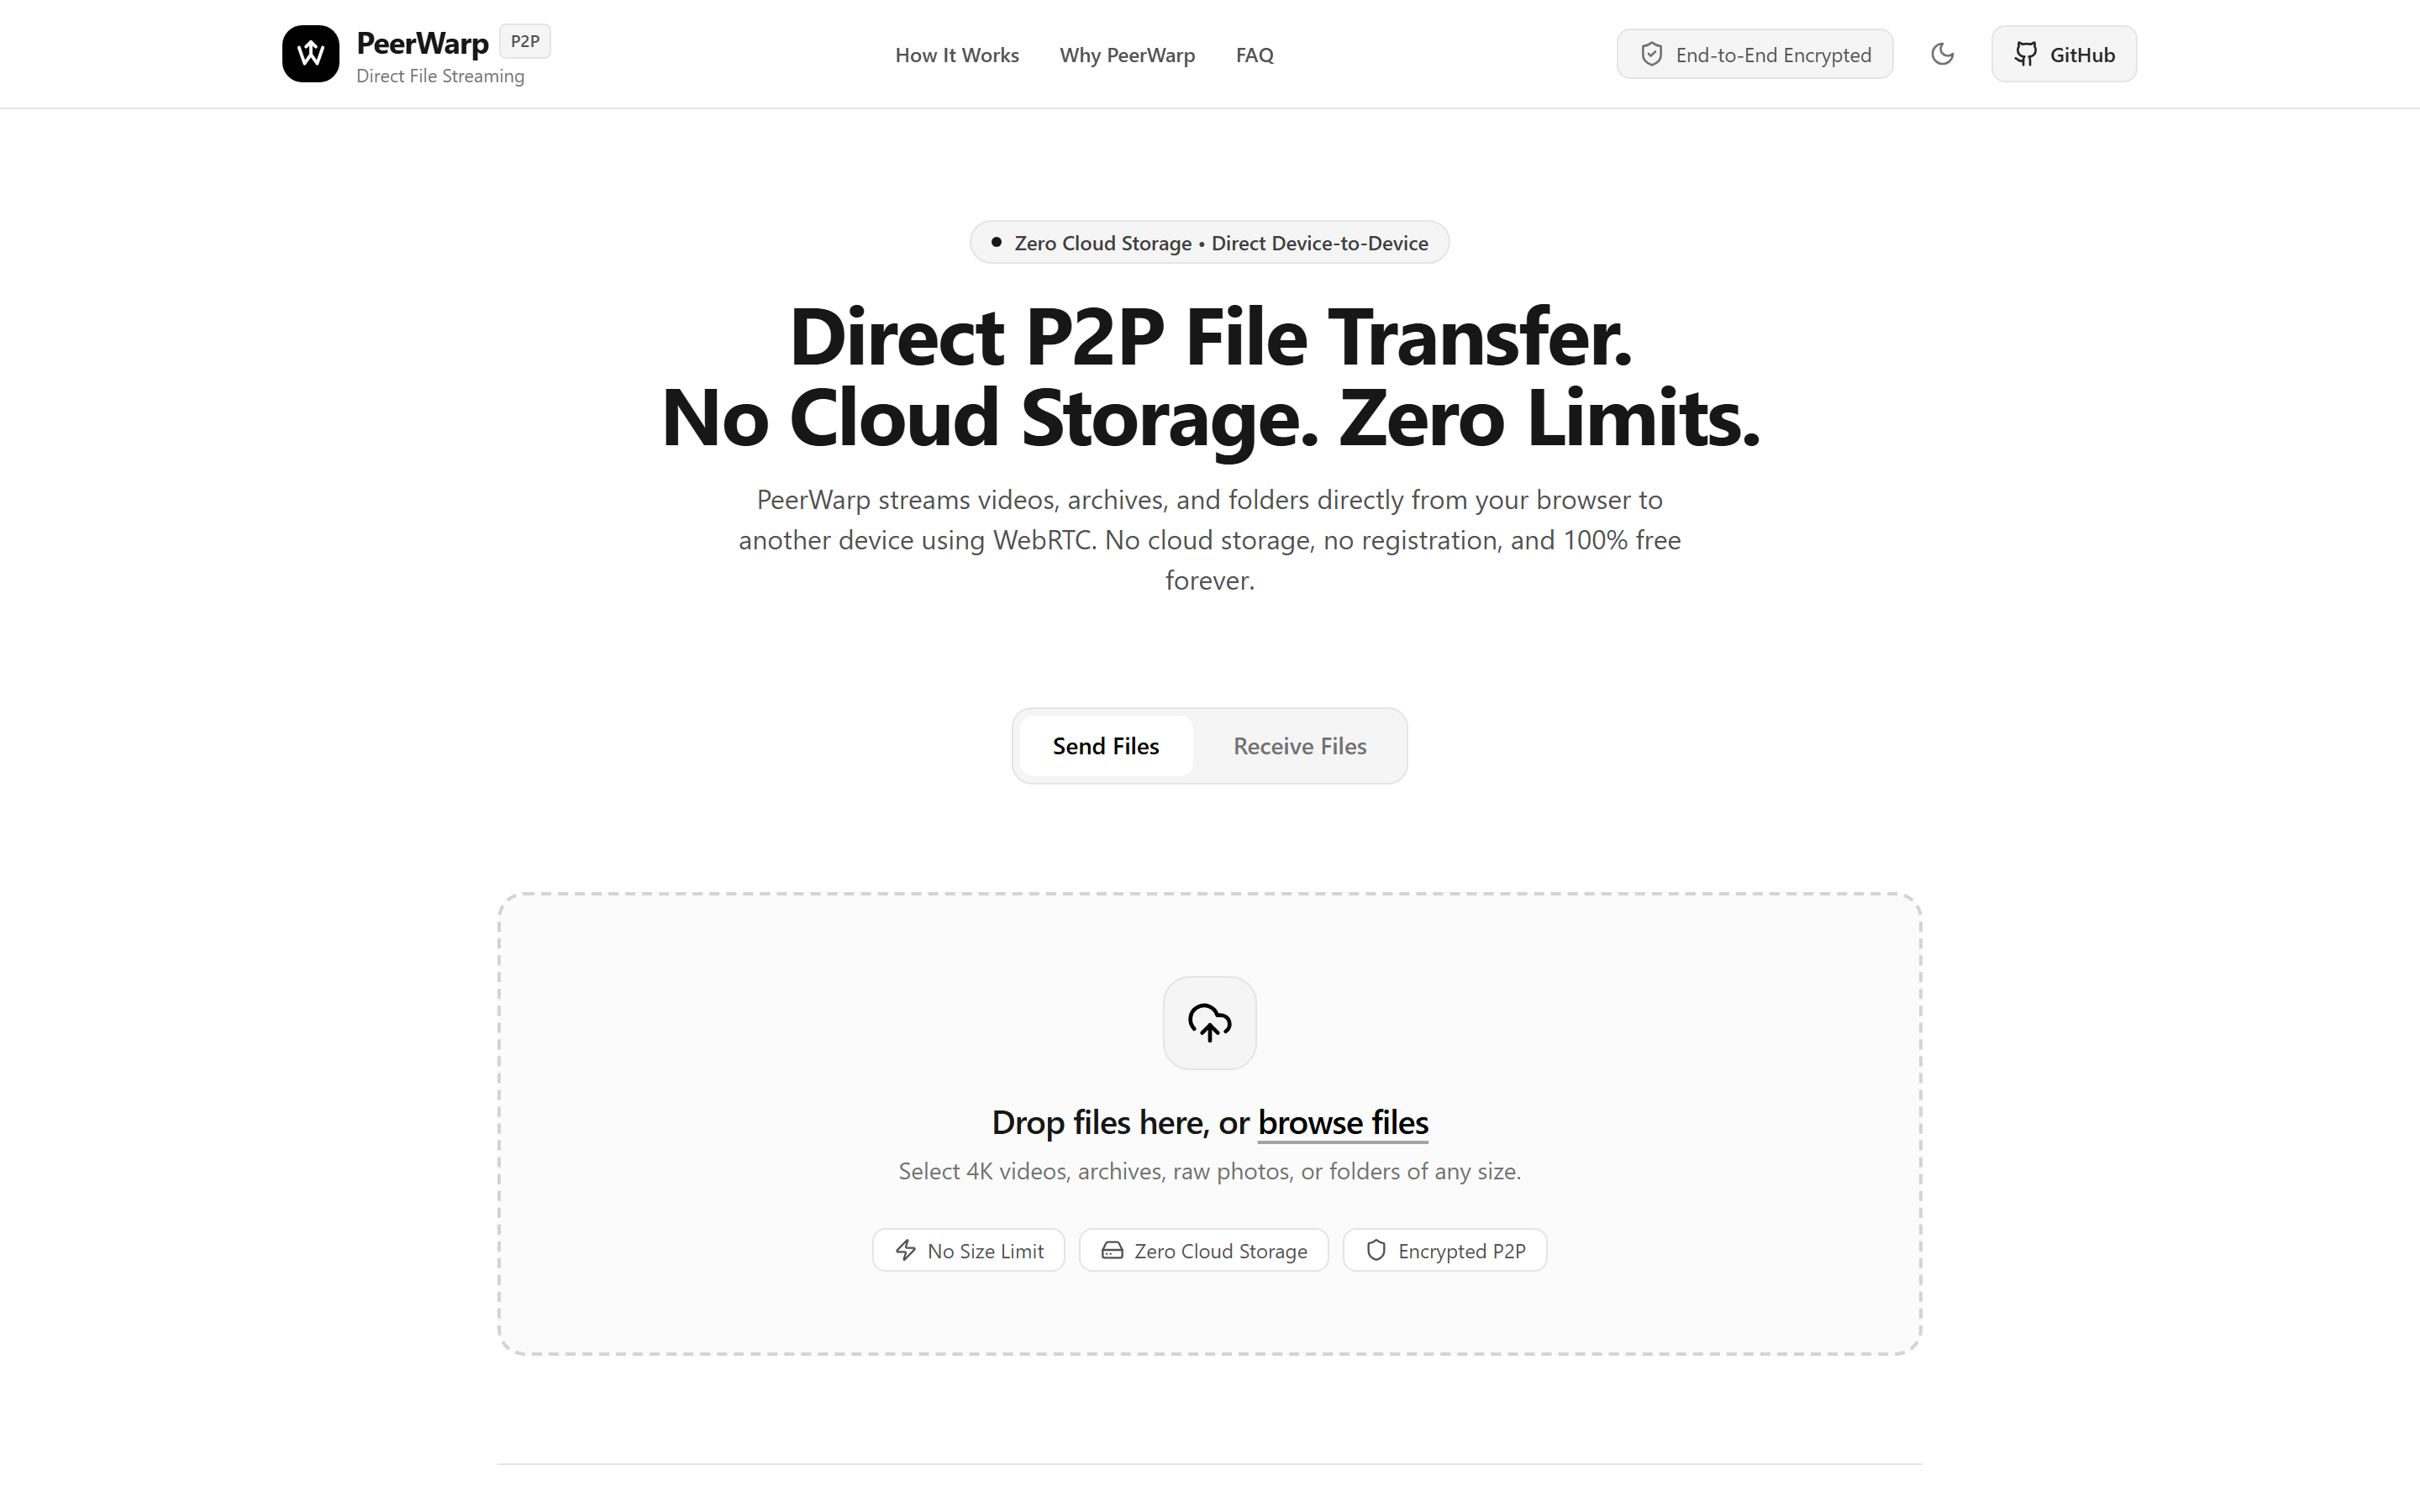
PeerWarp: Zero-Cloud P2P Direct File Transfer Platform
An open-source, production-grade file transfer platform engineered to move unlimited files and folders directly between browsers via encrypted WebRTC DataChannels, eliminating cloud storage intermediaries with direct-to-disk writing, on-the-fly compression, and local Wi-Fi radar.
 Cloud Engines & Infrastructure
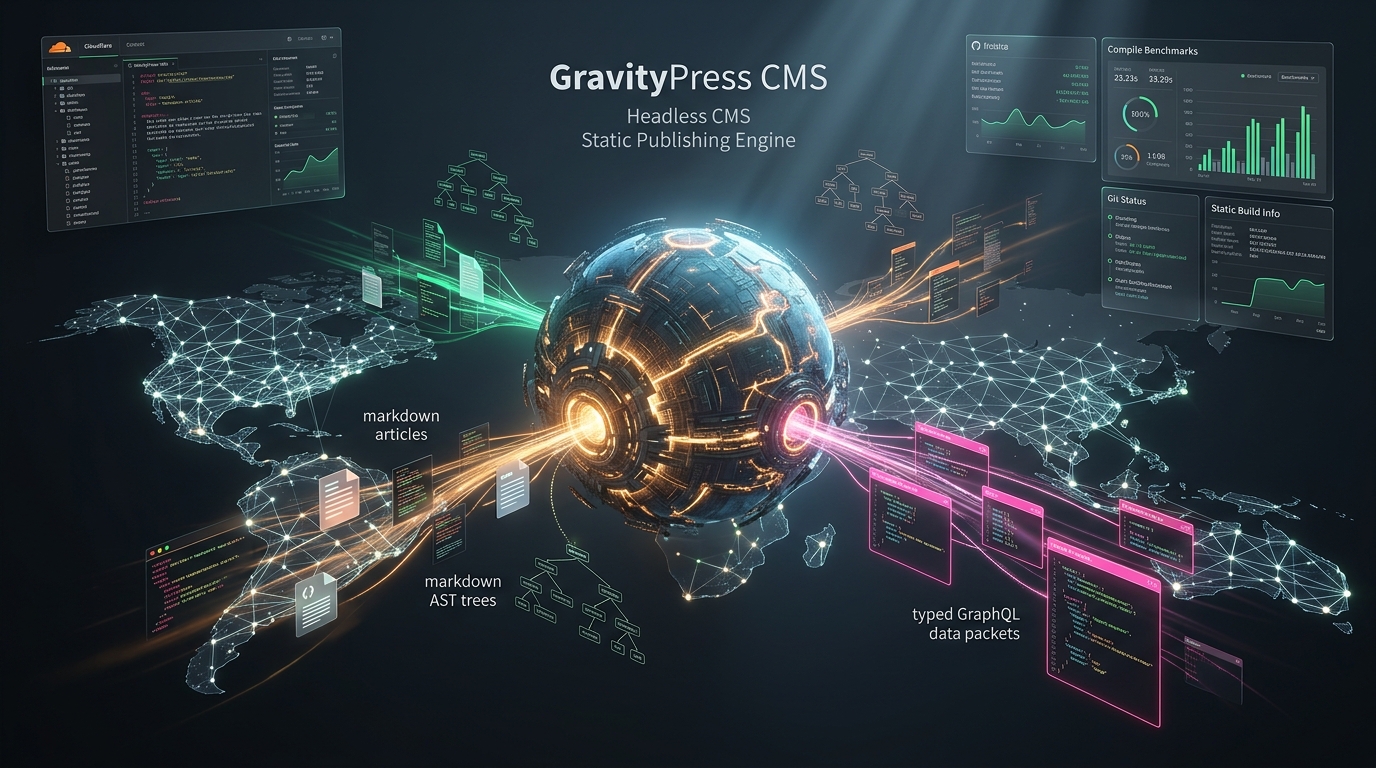
GravityPress CMS: High-Performance Headless Git-Based Content Engine & Static Site Generator
An ultra-fast, decoupled headless content management system and static publishing engine engineered with FastAPI, Strawberry GraphQL, in-memory BM25 search, automated Git version control, and native free Cloudflare Pages edge distribution.
 ERP & Enterprise Systems
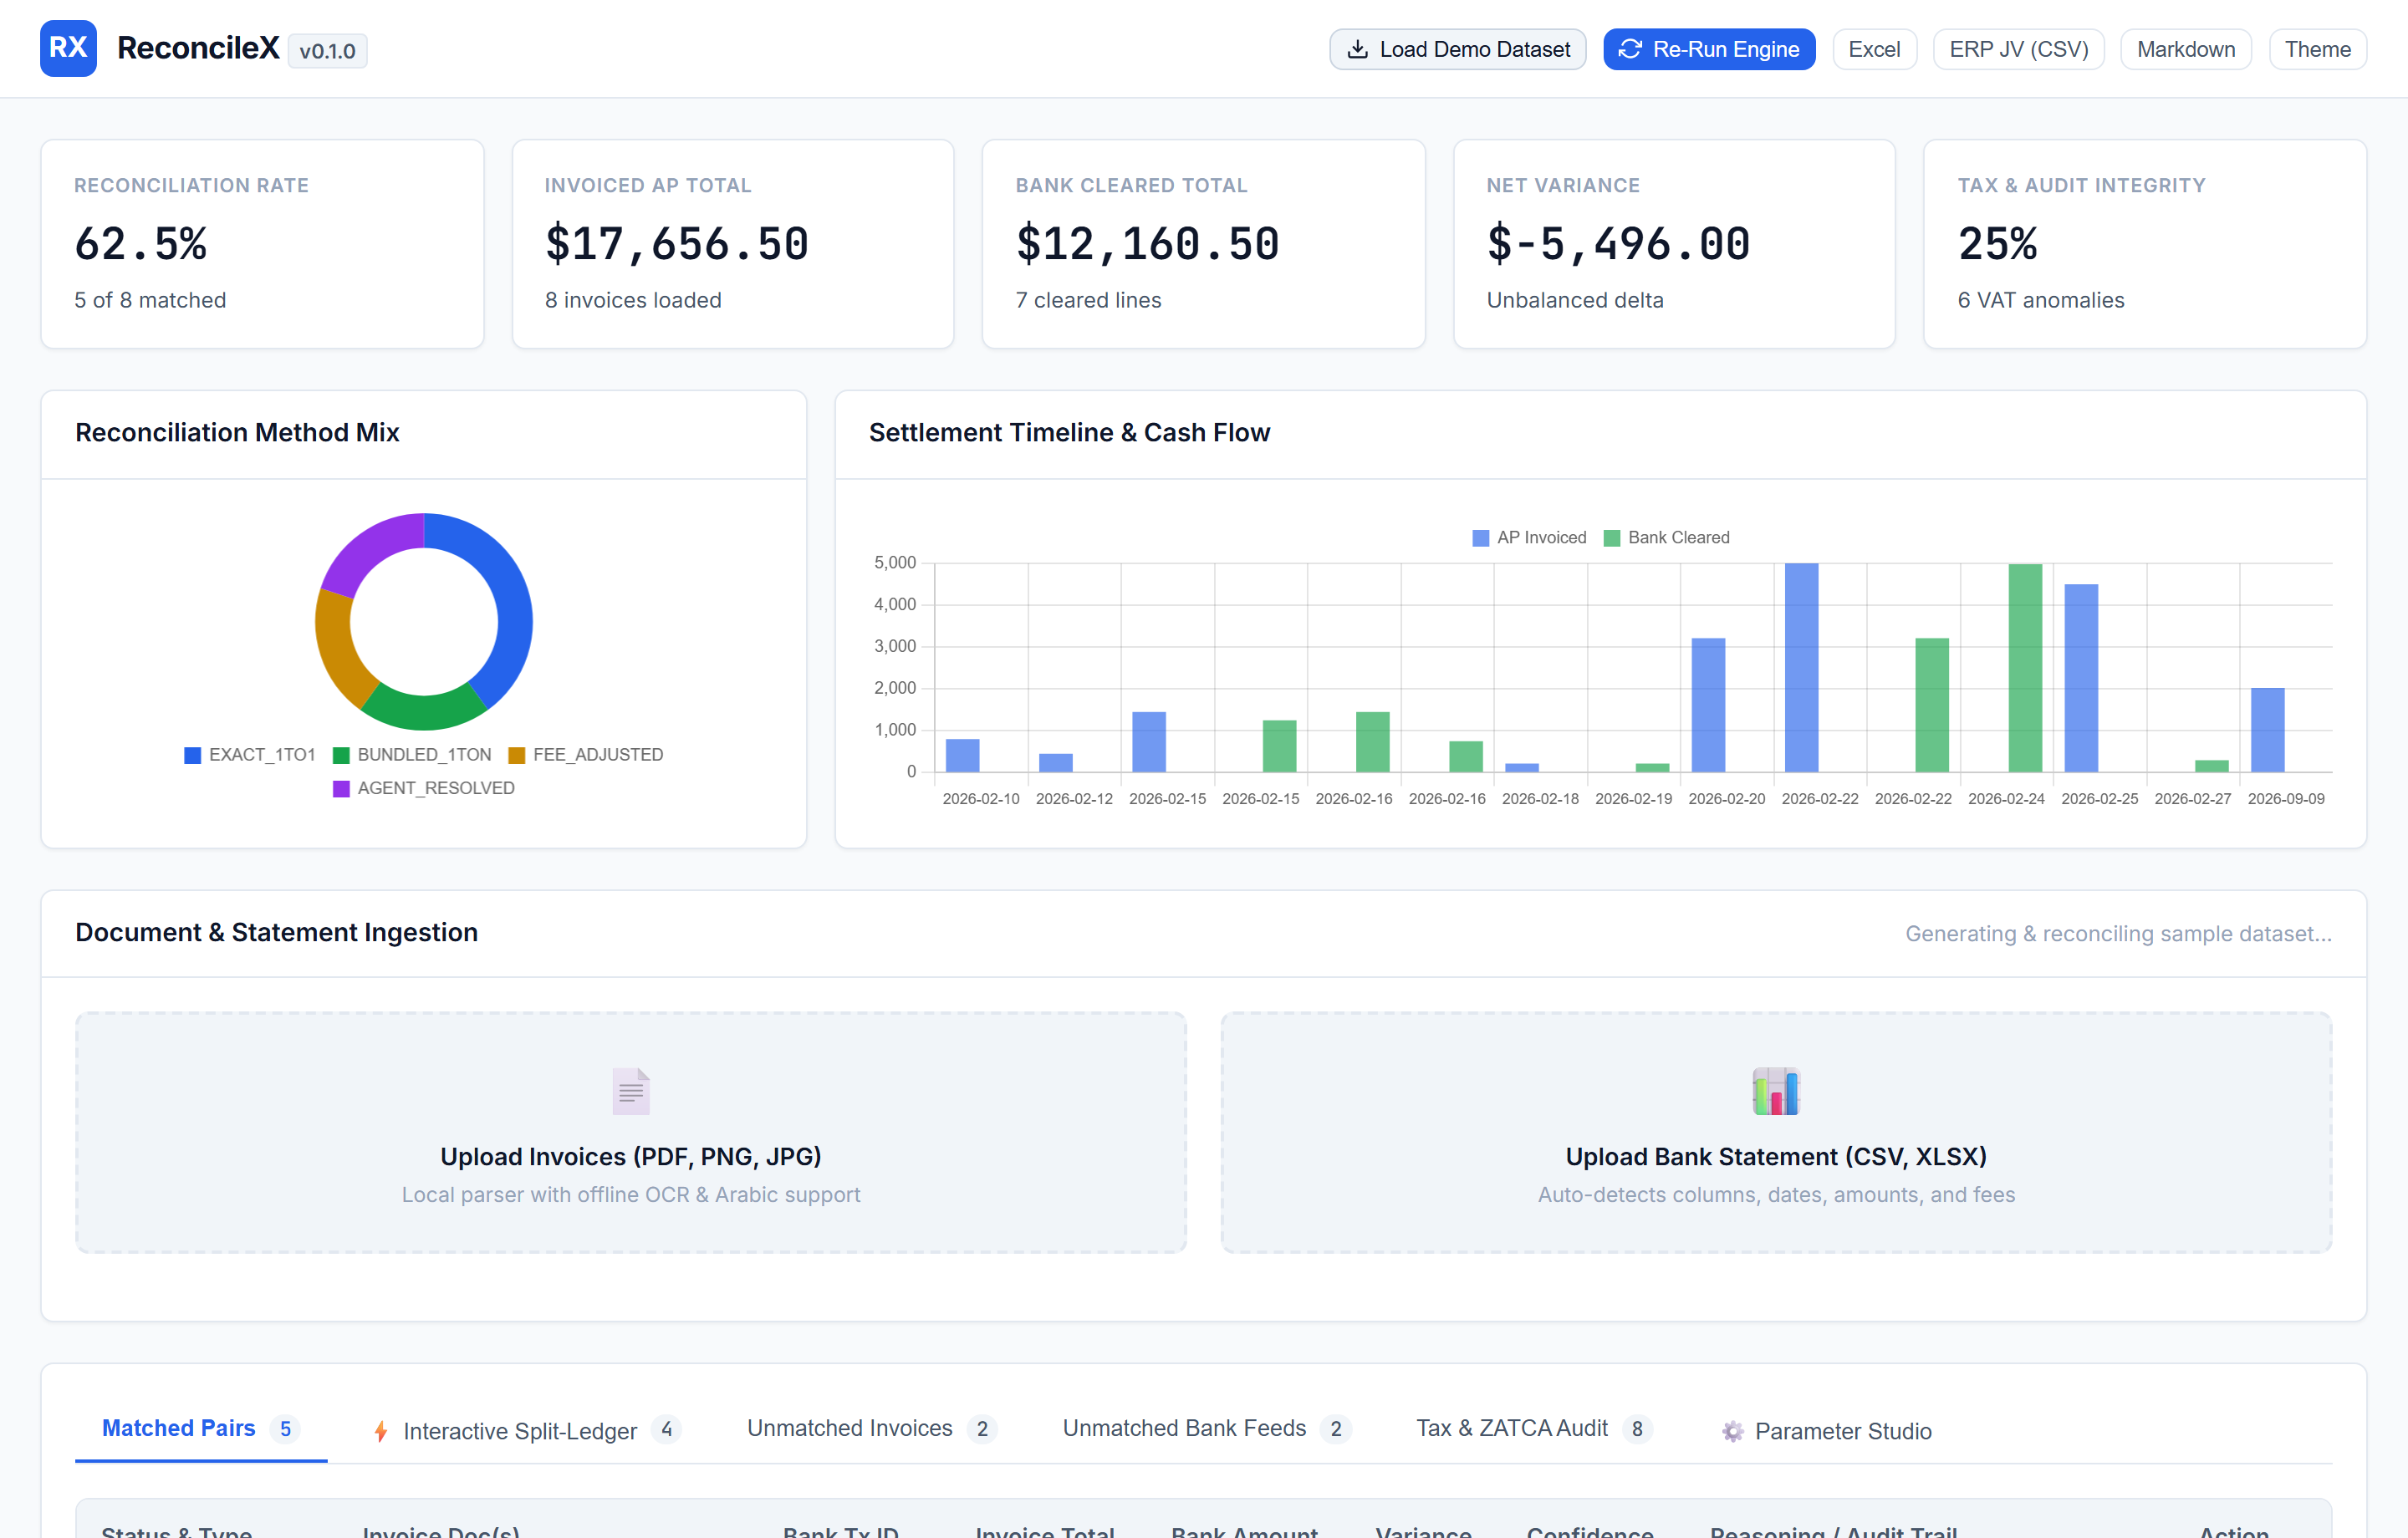
ReconcileX: Enterprise Financial Reconciliation & ZATCA Tax Compliance Platform with Hybrid Deterministic Architecture
An enterprise-grade open-source financial reconciliation engine engineered to eliminate manual spreadsheet matching, combining deterministic zero-hallucination arithmetic with agentic reasoning to resolve bundled batch payouts, ZATCA VAT compliance audits, and balanced ERP journal vouchers.