
Whisper-Sub-Forge: AI Speech & Subtitle Engineering Studio
A high-performance AI speech-to-text, Voice Activity Detection, and subtitle engineering studio featuring sub-millisecond timestamp precision, multi-format exports, concurrent batch CLI, and an interactive Web Studio.
The Speech Engineering Dilemma: Synchronization and Format Fragmentation
Media organizations, digital production studios, and educational platforms handle thousands of hours of recorded conferences, lectures, and broadcasts that require accurate, synchronized transcription. While generic automatic speech recognition models exist, transforming raw model output into broadcast-ready subtitle streams introduces major engineering challenges.
First, standard speech recognition models frequently suffer from timestamp drift and truncated phrasing, failing to distinguish between natural pauses and continuous speech. This creates subtitles that appear prematurely or linger awkwardly on screen. Second, high-throughput batch transcription traditionally requires dedicated graphical processing hardware, making lightweight local deployments cost-prohibitive. Third, the industry is heavily fragmented across incompatible captioning standards ranging from legacy broadcast formats with positioning tags to lightweight HTML5 web tracks.
Acoustic Architecture: Digital Signal Processing and Voice Activity Detection
To overcome these limitations, I engineered Whisper-Sub-Forge as a comprehensive speech and subtitle studio that unites acoustic signal processing with modern deep learning:
The ingestion pipeline begins with an audio inspection module that checks peak loudness, Root-Mean-Square signal energy, and sample rates. It automatically resamples arbitrary media into a normalized sixteen-kilohertz mono stream, establishing a consistent acoustic baseline regardless of input format.
To isolate speech intervals with high precision, the system executes an energy-based Voice Activity Detection algorithm. By analyzing thirty-millisecond sliding windows and monitoring zero-crossing rates alongside RMS amplitudes, the detector reliably flags vocal boundaries. An adaptive hangover smoothing filter prevents premature truncation on trailing syllables and quiet consonants, delivering tightly bounded speech cues to the recognition engine.
The core recognition pipeline bridges deep learning models with a deterministic acoustic synthesizer for zero-dependency offline operation. Extracted words undergo alignment routines that synchronize individual words down to a twenty-millisecond threshold, ensuring perfect lip synchronization across video playback.
Multi-Standard Formatting and Parallel Batch Processing
The platform incorporates a versatile formatting layer designed to satisfy modern web and professional broadcast specifications:
Interactive Web Studio and Developer Tooling
The platform provides an ergonomic operating environment for transcriptionists, audio engineers, and developers:
The web studio features a sleek dark glassmorphism interface with an interactive audio player and live cue timeline editor. Users can scrub through audio waveforms, adjust timing intervals visually, and switch between subtitle formats instantaneously without re-running recognition.
For developer automation, the platform includes a rich command line interface built with Typer and Rich for launching batch transcription jobs and testing model parameters directly from terminal sessions, accompanied by a production-ready FastAPI REST service containerized with Docker for seamless microservice orchestration.
Click any screen below to inspect in high-resolution with zoom in, zoom out, pan, and full screen controls.
 01
Interactive Subtitle Studio & Timeline Editor
Live cue timeline editor allowing audio playback scrubbing, transcript editing, and instant format conversion.
 02
FastAPI REST Gateway & OpenAPI Documentation
High-throughput endpoints for media transcription, subtitle conversion, and automated pipeline integration.
Interested in a similar project?
We can build a tailored solution customized to your business goals.
Explore Related Work
Production software, AI tools, and enterprise platforms.
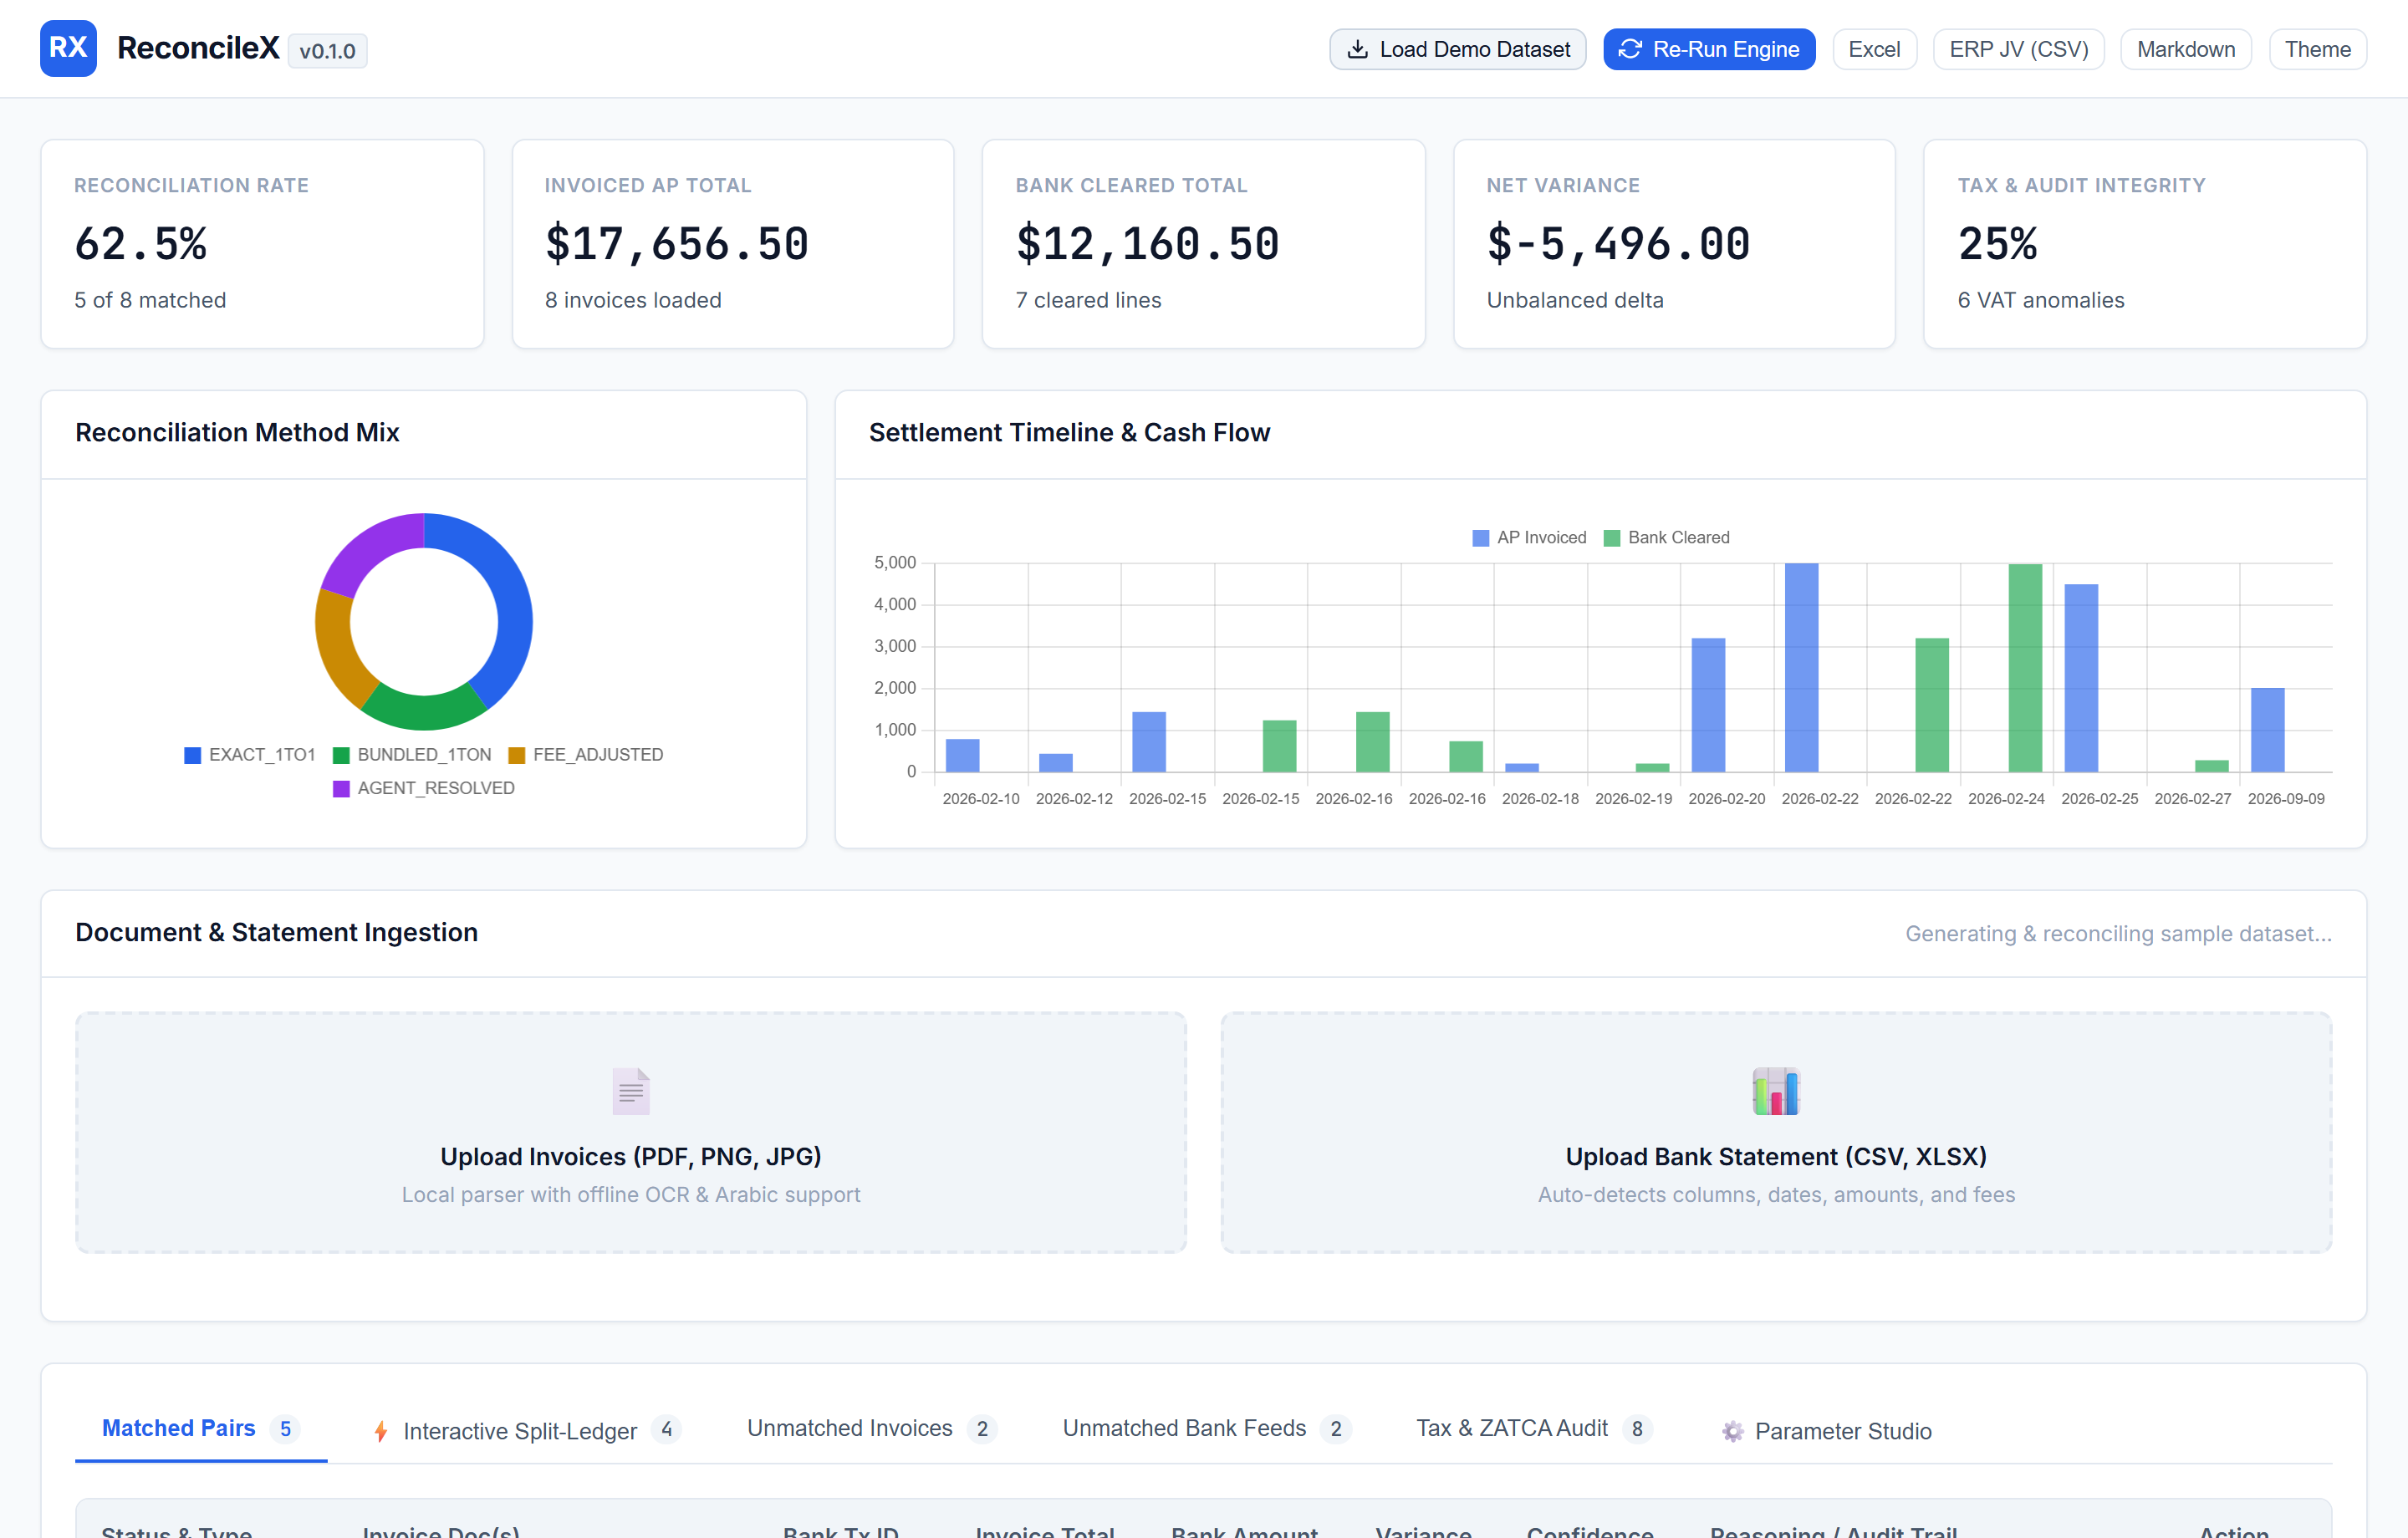 ERP & Enterprise Systems
ReconcileX: Enterprise Financial Reconciliation & ZATCA Tax Compliance Platform with Hybrid Deterministic Architecture
An enterprise-grade open-source financial reconciliation engine engineered to eliminate manual spreadsheet matching, combining deterministic zero-hallucination arithmetic with agentic reasoning to resolve bundled batch payouts, ZATCA VAT compliance audits, and balanced ERP journal vouchers.
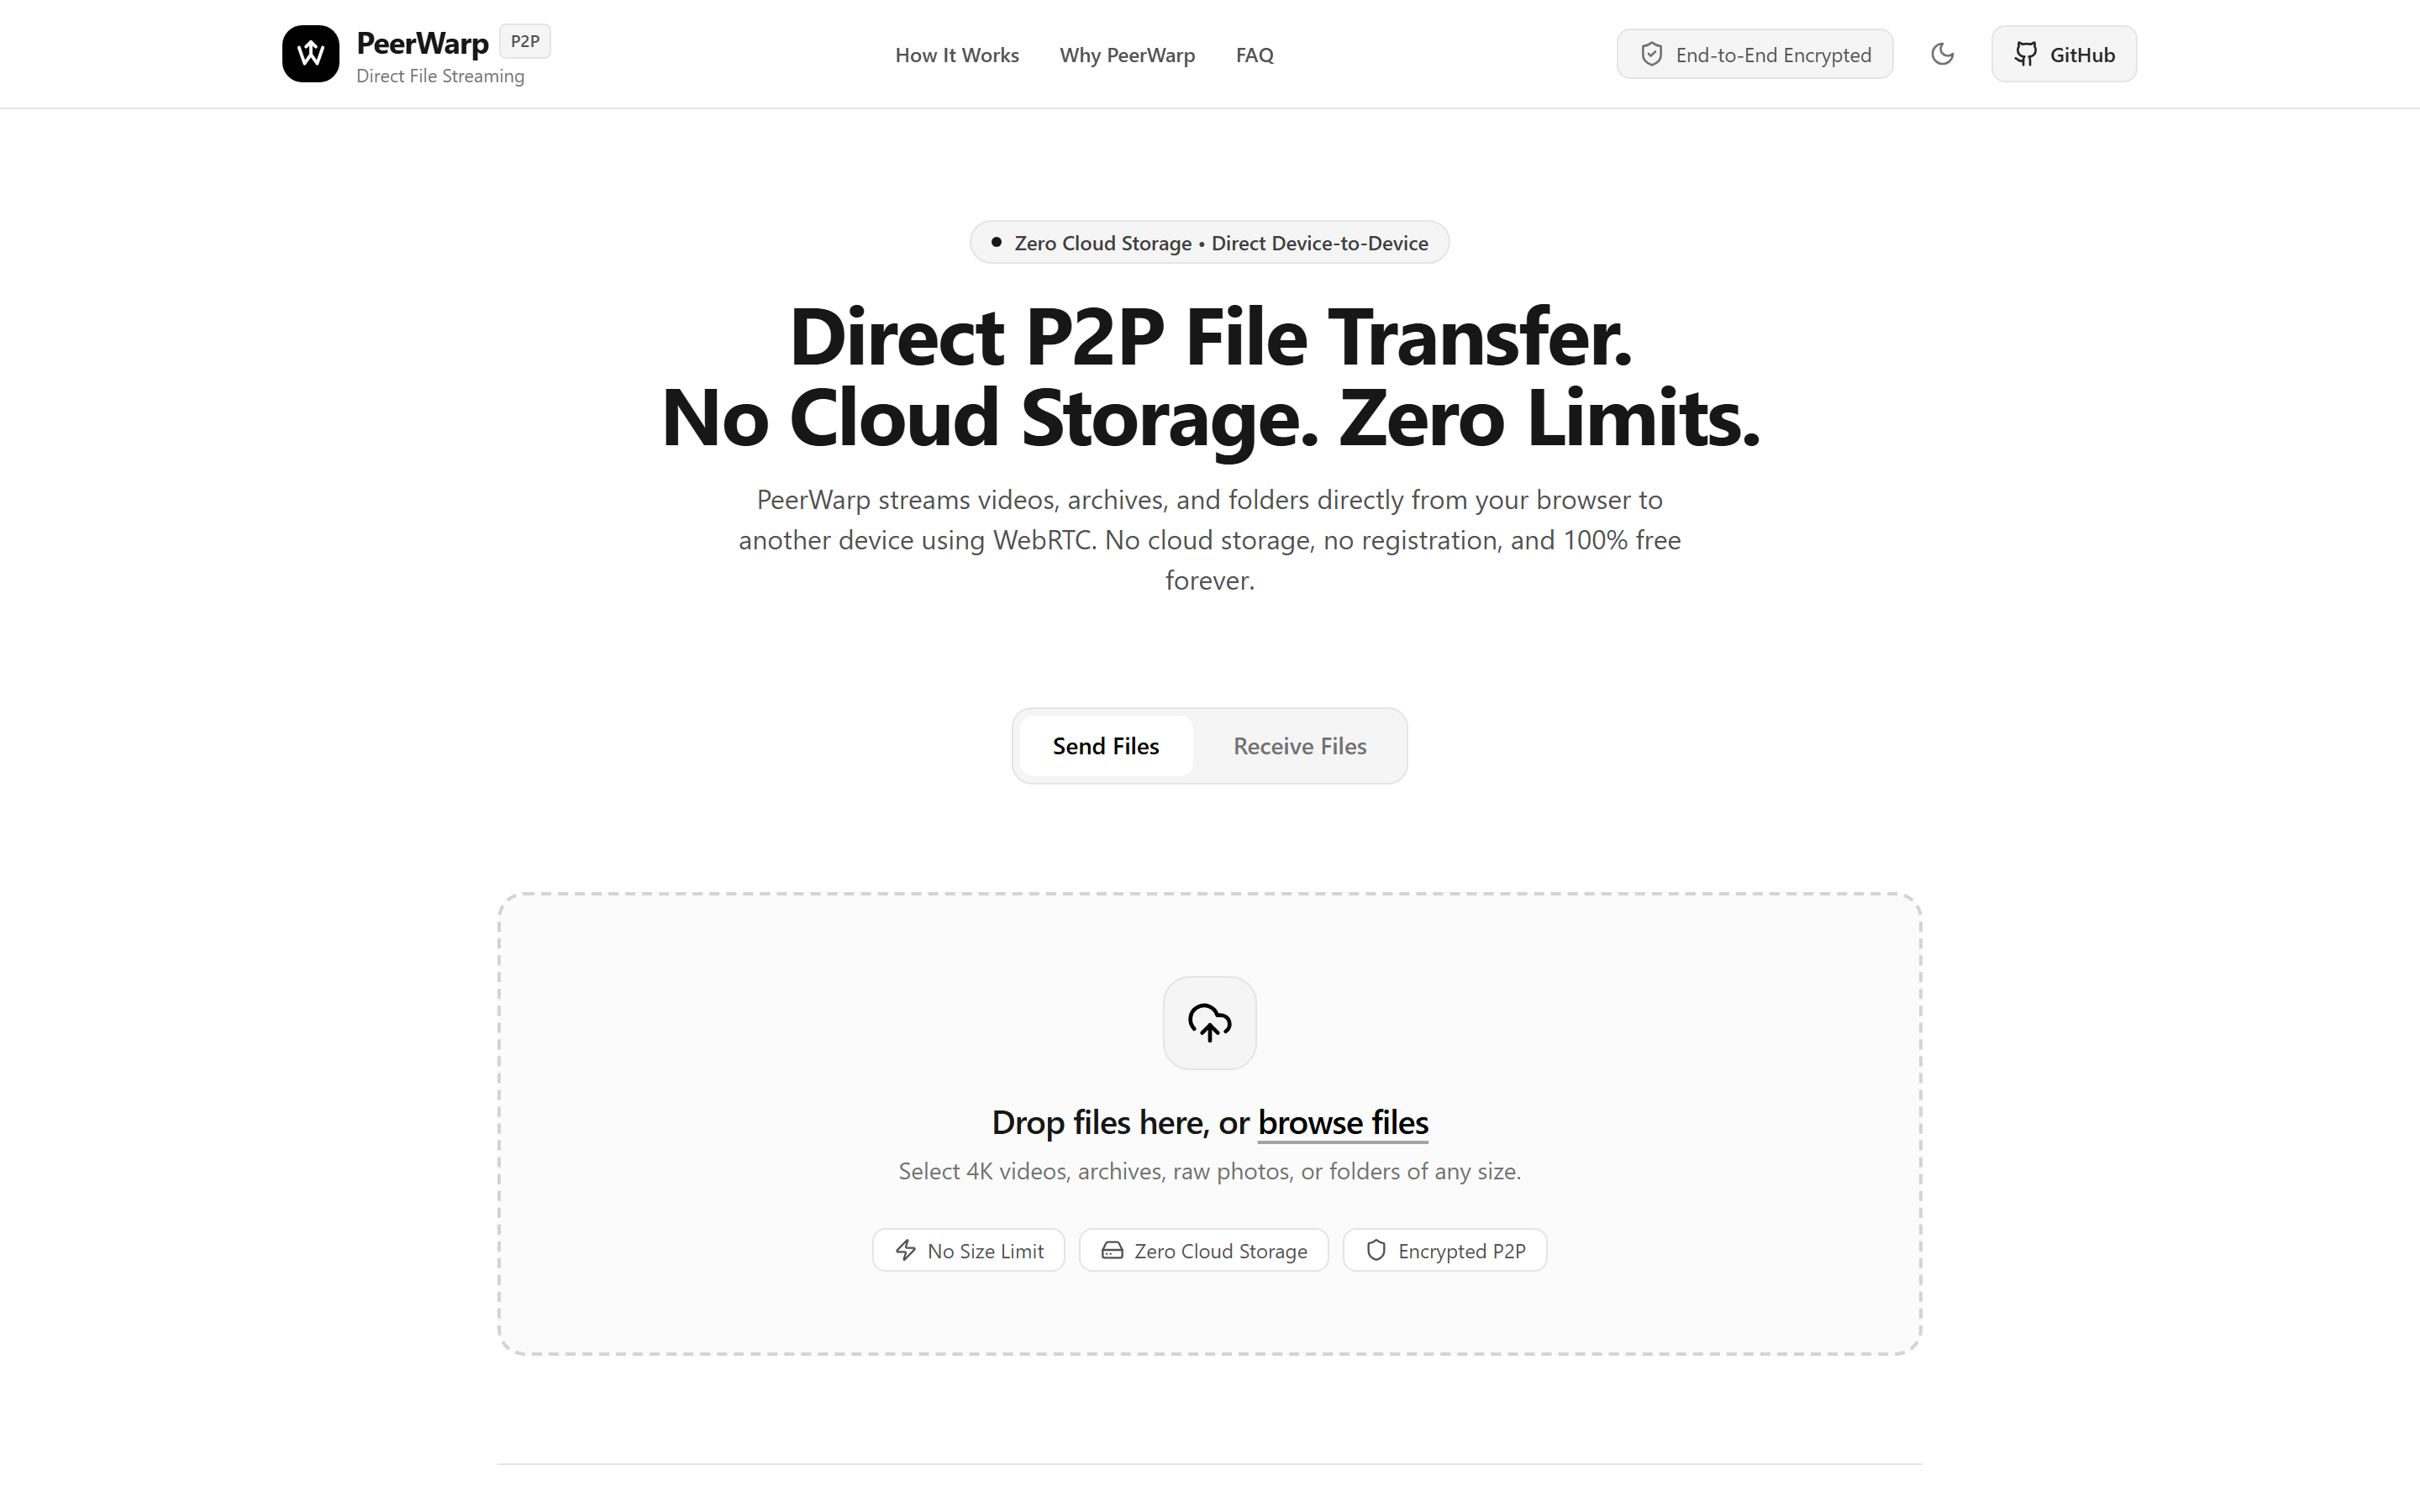 Cloud Engines & Infrastructure
PeerWarp: Zero-Cloud P2P Direct File Transfer Platform
An open-source, production-grade file transfer platform engineered to move unlimited files and folders directly between browsers via encrypted WebRTC DataChannels, eliminating cloud storage intermediaries with direct-to-disk writing, on-the-fly compression, and local Wi-Fi radar.
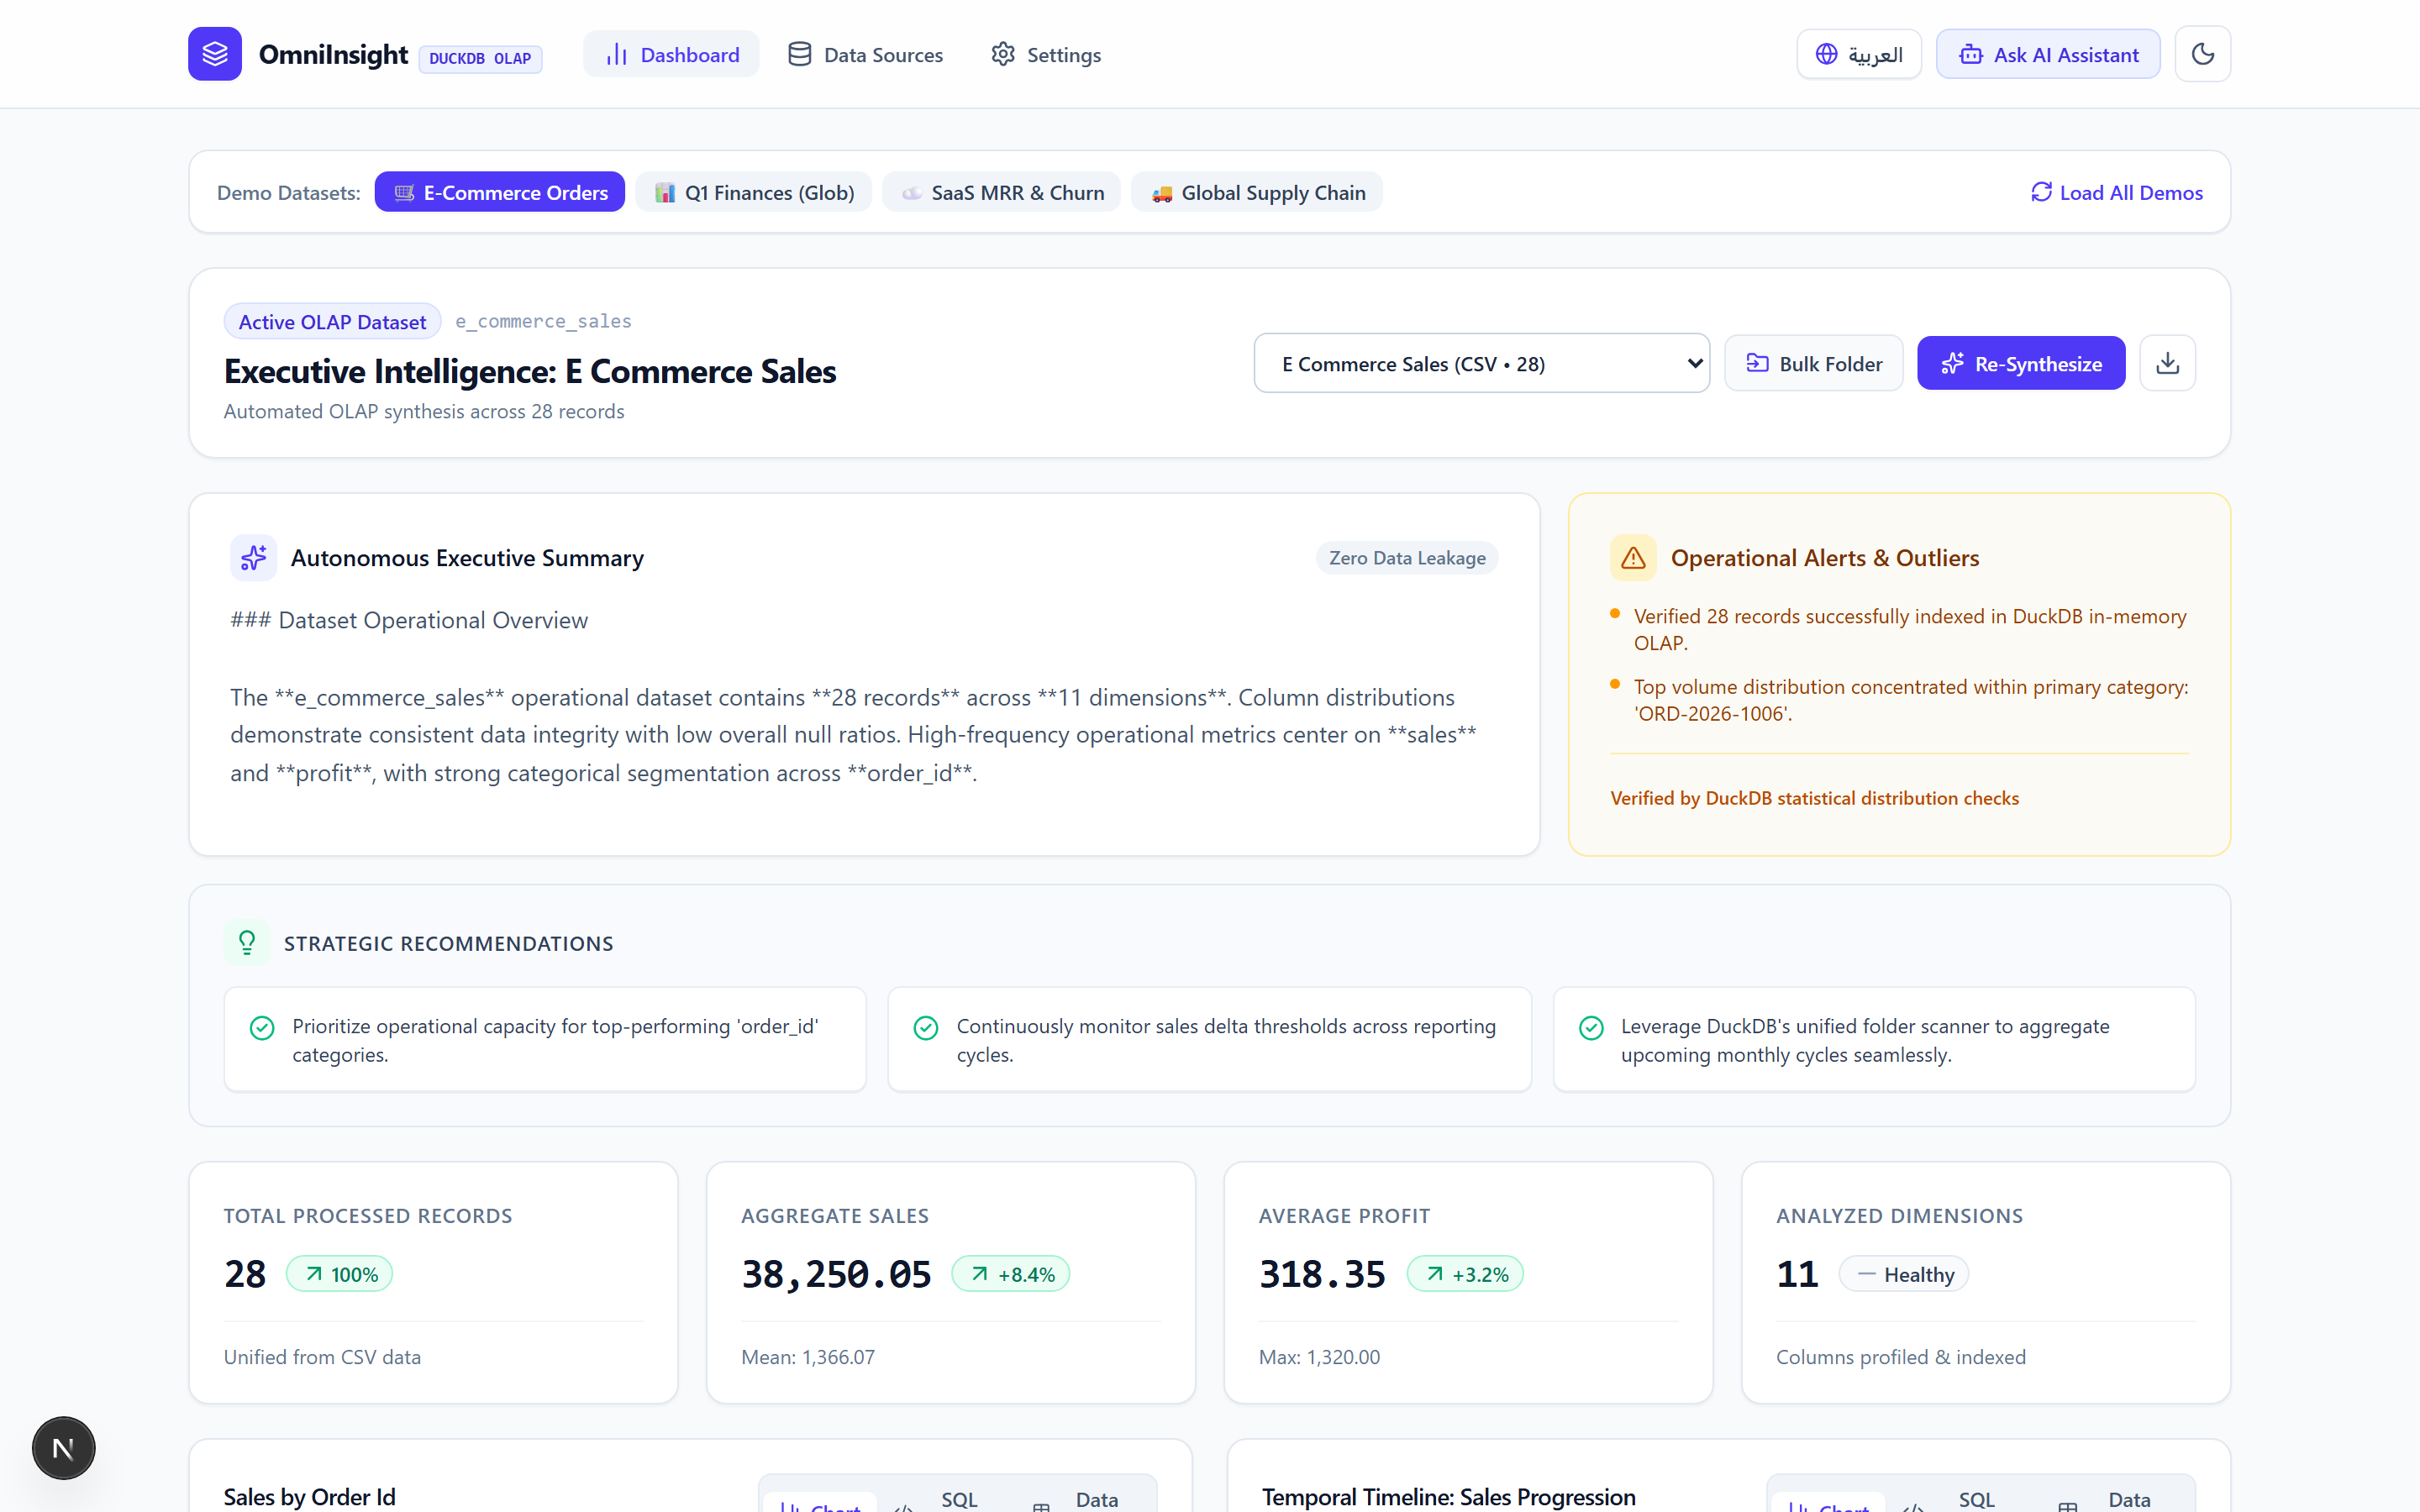 AI & Automation
OmniInsight: Privacy-Preserving Local BI & Automated Analytics Platform with In-Memory DuckDB and Multi-LLM Reasoning
An open-source, local-first Business Intelligence platform engineered to replace proprietary cloud BI tools, pairing DuckDB's vectorized in-memory OLAP engine with privacy-safe LiteLLM reasoning to autonomously synthesize executive dashboards and answer conversational NLQ queries with zero data leakage.